In the previous article, I explained the broader idea behind how I generate and sort trading algorithms. The main principle is simple: I do not search for one perfect strategy. I search for combinations of markets, templates, and timeframes that repeatedly produce groups of statistically healthy strategies.
In this second part, I want to go one level deeper.
This time, I will show how I organize my StrategyQuant projects, how I configure individual builds, how I retest generated strategies, and — most importantly — how I decide which combinations are worth continuing with and which ones I simply discard.
The video below shows the complete workflow inside StrategyQuant.
From Templates to Custom Projects
The starting point is our strategy templates.
Instead of manually creating every build from scratch, I use these templates as the foundation for a structured set of custom StrategyQuant projects.
I divide the projects into four main groups:
- Symmetric Breakouts
- Symmetric Pullbacks
- Asymmetric Breakouts
- Asymmetric Pullbacks
This structure allows me to keep different types of trading logic separated while still applying the same research methodology to all of them.
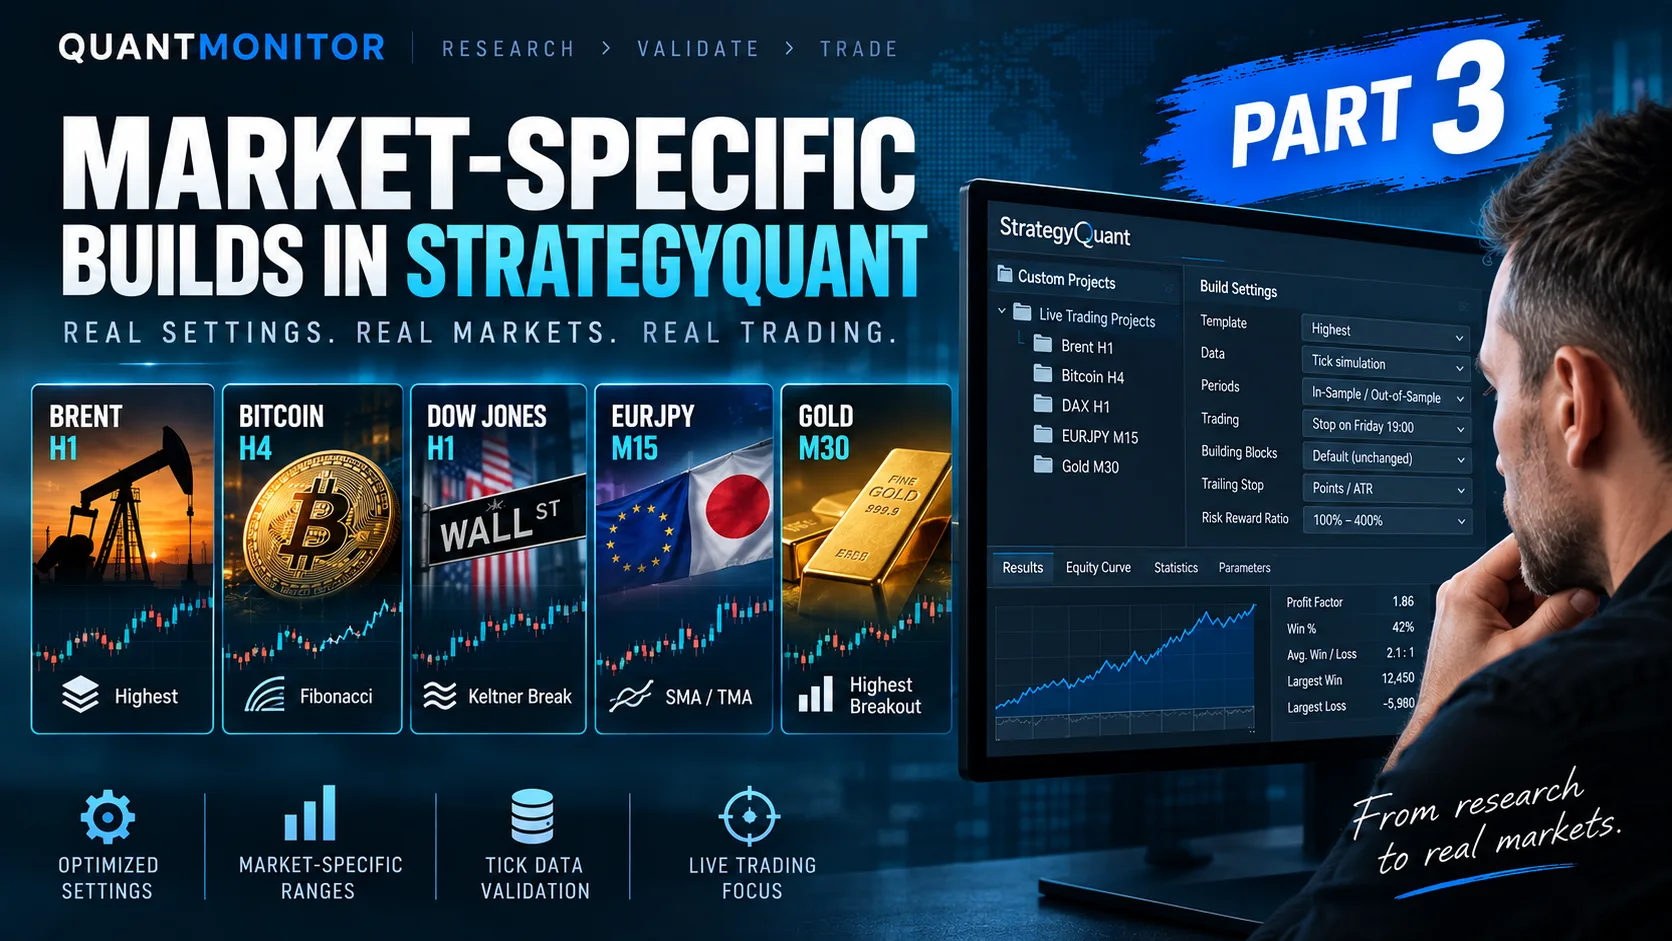
Inside these groups, I then create builds for individual markets.
For example:
- Brent
- Bitcoin
- DAX
- Dow Jones
- and other futures, indices, commodities, or markets I want to test
Every custom project therefore represents a very specific combination of three things:
Ticker + Timeframe + Template
That combination is the basic research unit of the whole process.
Two Timeframes for Every Template
For every template, I normally test two different timeframes.
For example, I may have one Brent Bollinger Break build on one timeframe and another Brent Bollinger Break build on H1.
With nine templates and two timeframes, this gives me:
9 templates × 2 timeframes = 18 builds per ticker
When this is repeated across multiple markets, the number of individual builds increases very quickly.
This is exactly why I prefer a standardized process.
I do not want to change dozens of parameters every time I move to another market. The initial settings remain largely identical, with predefined ranges broad enough to cover the basic requirements of the build.
The purpose of this stage is not to optimize every market individually.
The purpose is to give different market-template-timeframe combinations a comparable environment and see which ones naturally perform better.
Standardization Is Important
One of the biggest risks in algorithmic research is giving a weak idea too much attention.
If one market does not produce good strategies, it is very tempting to start changing parameters, widening ranges, adding conditions, or otherwise forcing the build to work.
I try to avoid that.
At this stage, I actually want some combinations to fail.
If the same general build logic produces strong results on one combination and consistently poor results on another, that information is valuable.
The build itself becomes a test of whether there is enough exploitable structure in that particular combination of market, timeframe, and template.
Retesting on Real Tick Data
After the initial generation phase, the strategies that pass my basic filters move to another important stage:
retesting on real tick data.
This is an essential part of my workflow.
A strategy can look attractive during the initial generation process, but I want to know whether its characteristics remain acceptable when the backtest is recalculated using higher-quality data.
Once the tick retest is completed, the surviving strategies are automatically stored in their corresponding folders.
The naming structure remains straightforward, for example:
Brent Bollinger Break 15
This makes it easy to trace every strategy back to the exact market, template, and timeframe combination that generated it.
The Databank Is Where the Real Sorting Starts
Each of my builds is configured to keep up to approximately 3,000 strategies in the databank.
But having 3,000 strategies does not mean I have 3,000 useful strategies.
The interesting part begins when I sort them.
One of the primary metrics I use for the initial ranking is:
Return / Drawdown Ratio
This immediately gives me a useful overview of how strong the entire build actually is.
And this is where an important part of my methodology comes into play.
I Judge the Combination, Not Only the Best Strategy
Some combinations of ticker, timeframe, and template simply do not work particularly well.
For example, I may run a complete build where even the best strategies achieve a Return / Drawdown Ratio of only around 4 or 4.5.
At the same time, the population may show large variations in stability.
I usually do not spend much additional time on these combinations.
I discard them.
On the other hand, some builds generate a completely different profile.
After the initial tick retest, I may see a population containing multiple strategies with Return / Drawdown Ratios above 8 or even 10.
Those are the combinations I write down and investigate further.
This is a major distinction.
I am not asking:
“Which is the best strategy in this databank?”
I am asking:
“Which ticker, timeframe, and template combination is capable of repeatedly generating strong strategies?”
That question is much more useful.
Searching for Productive Strategy Clusters
After repeating this process across many builds, the original large research universe starts becoming much smaller.
Certain combinations disappear completely.
Others keep appearing near the top.
Eventually, I end up with relatively small groups of:
- tickers,
- timeframes,
- and templates
that repeatedly generate interesting strategies.
These are my productive research zones.
Instead of spending the same amount of time on every possible combination, I can now concentrate deeper validation work on areas where the generation process itself has already demonstrated a statistical advantage.
Then I Look at the Individual Strategy
Only after identifying an interesting build do I start looking more closely at individual strategies.
The first thing I usually inspect is the equity curve.
I want to understand what is actually producing the overall result.
I also look separately at:
- the long side,
- the short side,
- and the combined strategy.
A good combined equity curve can sometimes hide a weak component, so separating long and short performance gives me additional context.
The goal is not to find a perfectly smooth line.
The goal is to make sure that the strategy behaviour makes economic and statistical sense.
Winning Percentage
The next statistic I check is Winning Percentage.
For the type of systems I develop, I generally consider a realistic range to be approximately:
30% to 50%
A lower winning percentage is not automatically a problem, especially in breakout systems.
But the relationship between win rate, average winner, average loser, and overall expectancy needs to make sense.
This leads directly to the next metric.
Profit Factor
I also look at the Profit Factor.
As an initial guideline, I generally want to see:
Profit Factor > 1.35
Again, I do not use this as an isolated pass/fail metric.
A Profit Factor of 1.50 tells me very little without knowing the number of trades, drawdown behaviour, average trade characteristics, robustness, and how the equity curve was created.
But as part of the complete statistical profile, it is useful.
Average Win vs. Average Loss
One of the most important pieces of information for me is the relationship between:
Average Win and Average Loss
Ideally, I like to see something around:
2:1
In other words, the average winning trade is approximately twice as large as the average losing trade.
I do not require every system to hit exactly this number.
Depending on the strategy logic, something slightly above 1:1 can still be acceptable.
But I want this relationship to be statistically reasonable.
If the strategy has a relatively low win rate and its average winner is barely larger than its average loser, the system becomes much less attractive.
The statistics have to work together.
Largest Winning and Losing Trades
I also inspect:
- Largest Winning Trade
- Largest Losing Trade
This is a simple but very important check.
I want to know whether the strategy’s performance is driven by its normal trading behaviour or by one or two extreme outliers.
Imagine a strategy with an excellent total return, but a huge percentage of that return comes from a single unusually large trade.
The headline statistics may still look attractive.
But statistically, the strategy may be much less healthy than it first appears.
The same applies to extreme losing trades.
This is why I always look beyond the headline metrics.
No Single Metric Decides Everything
This is probably the most important point of the whole process.
I do not have one magic number that decides whether a strategy is good.
Return / Drawdown Ratio matters.
Profit Factor matters.
Winning Percentage matters.
Average Win and Average Loss matter.
The long and short equity curves matter.
The largest winners and losers matter.
But none of them should be evaluated completely independently.
What I am looking for is a healthy statistical profile.
Even more importantly, I want to see that healthy profile across a group of strategies generated from the same underlying combination.
That gives me much more confidence than discovering one exceptional backtest.
The Real Goal of the Build Process
The purpose of these builds is therefore not simply to generate algorithms.
The deeper purpose is to map the research space.
I want to discover where my templates interact well with specific markets and timeframes.
A weak combination might generate thousands of strategies without producing anything genuinely interesting.
A strong combination may consistently create a cluster of strategies with:
- high Return / Drawdown Ratios,
- reasonable Profit Factors,
- realistic winning percentages,
- healthy Average Win / Average Loss relationships,
- acceptable long and short performance,
- and no obvious dependency on extreme trades.
Those are the combinations I want to keep.
Everything else can be removed from the research pipeline.
Filtering Before Optimization
There is also a broader principle behind this workflow.
Filter first. Optimize later.
It is very easy to spend weeks optimizing a weak idea.
StrategyQuant gives us enormous power to generate and test combinations, but that power can also lead to overfitting if every disappointing result becomes another reason to modify the build.
My preference is different.
I want the initial research process to tell me where the strongest opportunities are.
Only then does it make sense to spend more computational power and research time on advanced validation, parameter analysis, walk-forward testing, cross-market testing, and final portfolio construction.
My Basic Workflow
The complete process can be summarized like this:
- Start with predefined strategy templates.
- Divide them into logical custom-project groups.
- Create individual ticker-timeframe-template combinations.
- Use two timeframes for each template.
- Run standardized builds.
- Keep up to approximately 3,000 strategies per databank.
- Retest selected strategies using real tick data.
- Sort the results primarily by Return / Drawdown Ratio.
- Eliminate weak ticker-timeframe-template combinations.
- Keep combinations capable of generating strong strategy clusters.
- Inspect individual equity curves.
- Compare long and short performance.
- Check Winning Percentage.
- Check Profit Factor.
- Compare Average Win with Average Loss.
- Inspect the largest winning and losing trades.
- Move only the strongest candidates into deeper robustness testing.
This gives me a repeatable workflow instead of making subjective decisions every time I open a new backtest.
The Key Idea
If there is one idea I want you to take away from this article, it is this:
Do not search only for good strategies. Search for environments that repeatedly generate good strategies.
A single strategy can be lucky.
A productive combination of market, timeframe, and strategy logic is much more interesting.
That is why I spend so much time sorting entire builds before becoming interested in individual algorithms.
The initial generation process gives me thousands of candidates.
The sorting process tells me where the real research should begin.
What Comes Next
This is still only one part of the complete development workflow.
Once I have identified strong strategy groups, the next step is much deeper validation.
That includes testing whether the strategies remain stable when conditions change, whether their parameters sit inside a functional neighbourhood rather than on an isolated optimum, and whether the edge survives additional robustness testing.
That is where the difference between an attractive backtest and a potentially robust trading system becomes much clearer.
More on that in the next part.
Disclaimer: This content is for educational and research purposes only. Trading and investing involve substantial risk. Strategy examples, backtests, simulations, and hypothetical results have limitations and do not guarantee future performance. Past performance is not necessarily indicative of future results.