In the previous article, I explained how I organize my StrategyQuant builds, how I filter large groups of generated strategies, and how I identify combinations of tickers, timeframes, and templates that repeatedly produce strong results.
That process gives me a broad map of what works and what does not.
The next step is more specific.
Once I know which market-template-timeframe combinations are worth keeping, I stop using completely generic settings and start adapting the builds to the behaviour of individual markets.
This is what I want to show in this part.
The goal is no longer to explore everything.
The goal is to take the combinations that already showed potential and configure them more precisely for live trading research.
From General Research to Market-Specific Builds
In the earlier stage, I run broad cross-market research across:
- multiple instruments,
- multiple timeframes,
- and multiple strategy templates.
This gives me a very large sample of possible combinations.
From there, I can identify which combinations consistently produce the strongest groups of strategies.
Once I have this information, I create more focused custom projects.
Instead of asking:
“What works across the whole research universe?”
I now ask:
“What settings work best for this specific market?”
This is where the process becomes much more practical.
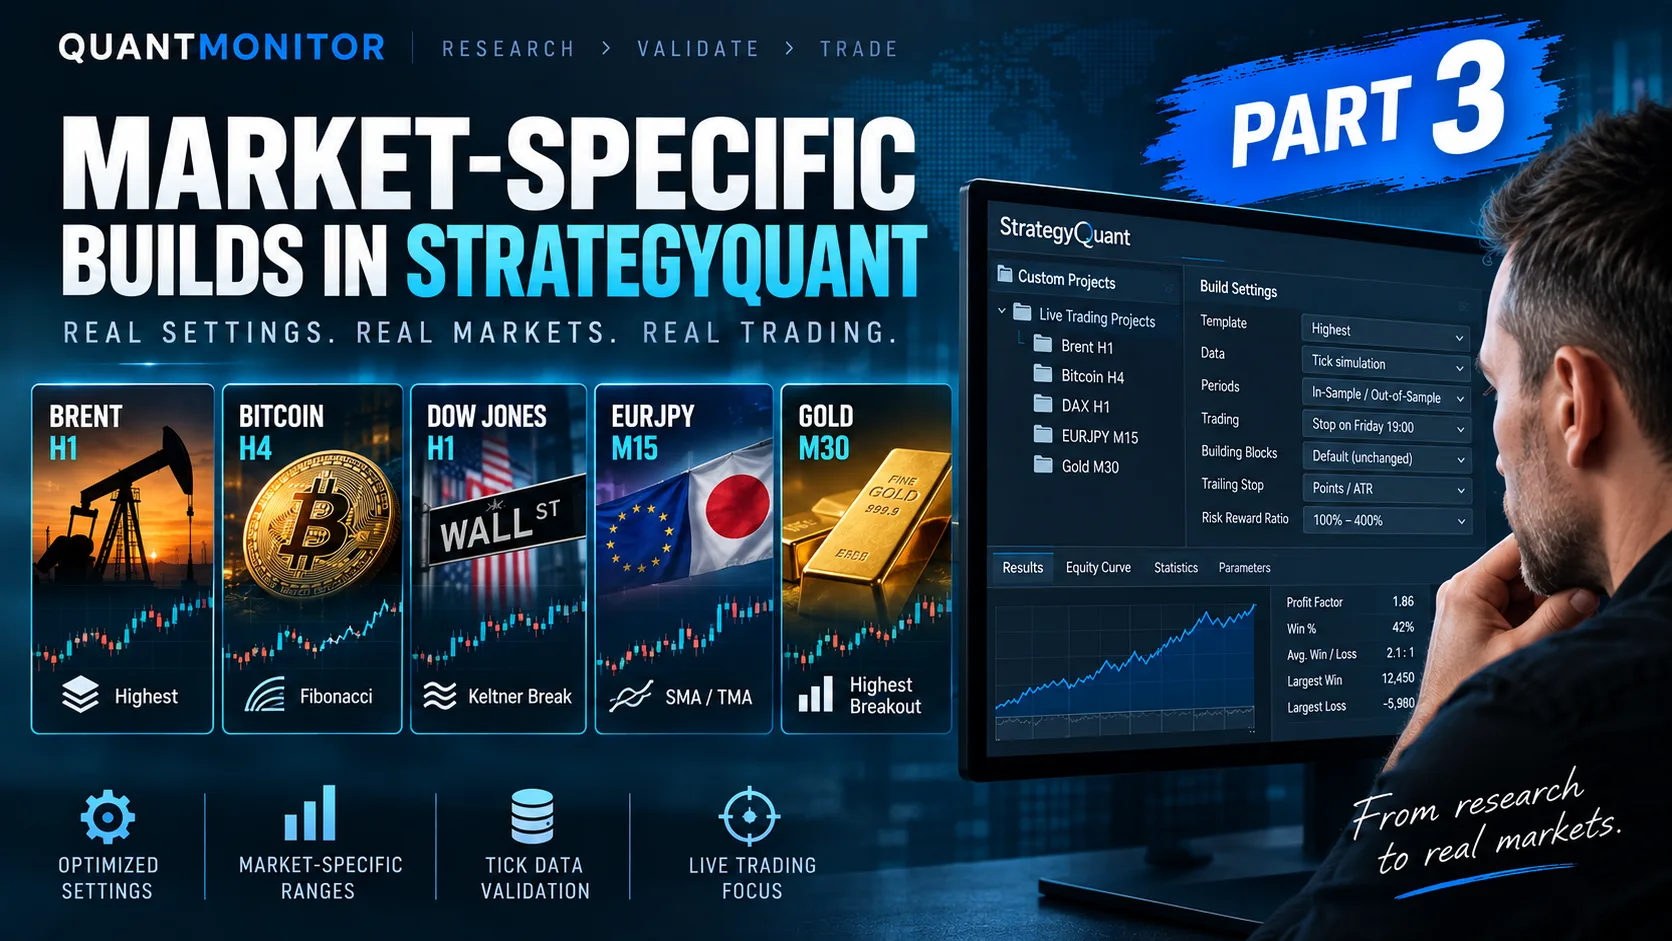
Brent on H1
One of the combinations that works well for me is:
Brent – H1
For this market, I use our Highest template.
At this stage, I already have a more specific configuration based on the results from the broader research phase.
The data are generated using tick simulation, and I keep the same general structure of:
- In-Sample
- Out-of-Sample
- True Out-of-Sample in the retest stage
This structure stays consistent across the different market-specific builds.
I also stop trading on Friday at 19:00.
The building blocks themselves remain largely unchanged.
The more important adjustment comes from the parameter ranges.
Market-Specific Take Profit and Stop Loss Ranges
One of the key points I have mentioned several times is that every market behaves differently.
Brent does not move like Bitcoin.
Bitcoin does not move like Euro Yen.
Gold does not move like Dow Jones.
Because of that, I do not believe in using identical Take Profit and Stop Loss ranges across all markets.
Instead, I adjust the point-based ranges according to:
- the volatility of the market,
- its typical daily and intraday movements,
- and the timeframe I am working with.
For one market I may use relatively tight point ranges.
For another, the same numerical values would be completely inappropriate.
This sounds obvious, but it makes a very large difference when building strategies systematically.
ATR or Fixed Pip Ranges
For some builds, I use ATR-based values.
For others, I prefer fixed pip or point ranges.
Both approaches can work.
The important thing is that the ranges need to make sense relative to the normal movement of the instrument.
For example, a fixed Stop Loss value that works well on Euro Yen M15 may be completely unsuitable for Gold M30.
The same applies to trailing stops and trailing activation.
These can also be configured using:
- fixed point ranges,
- ATR-based values,
- or other parameterized ranges.
I treat these settings as part of the market-specific research process.
Bitcoin on H4
For Bitcoin, the timeframe that works best for me is:
H4
On this market, I get particularly good results with our Fibonacci template.
Again, this is not something I assume in advance.
It comes from the broader research stage.
I first test many combinations.
Then I keep the ones that consistently generate better strategy populations.
Bitcoin H4 with the Fibonacci template is one of those combinations.
The important principle here is that I am not forcing every template to work on every market.
I let the data show me where the productive combinations are.
Dow Jones on H1
Another market I use is:
Dow Jones – H1
Here, I use the Keltner Break template.
The overall build structure stays the same.
I keep the same data segmentation and the same general validation process.
The main changes again come from the parameter ranges that are adapted to the movement characteristics of Dow Jones.
This is exactly why I separate the projects by market.
Once you start adjusting ranges properly, a single universal build becomes less useful.
Euro Yen on M15
Another combination I use is:
Euro Yen – M15
Here, I work with breakout logic based on moving averages.
More specifically, I use either:
- Breakout Simple Moving Average
- or Triple Moving Average
These templates are relatively similar in structure.
Again, the reason I use them is not because moving-average breakouts are universally superior.
They simply produced good results on this particular combination during the broader research phase.
That distinction is important.
Gold on M30
The fifth market in this group is:
Gold – M30
Here, I use our Highest Breakout template.
Gold is a good example of why market-specific ranges matter.
The typical movement of Gold is very different from a currency pair or an index.
Because of that, I adjust:
- Take Profit ranges,
- Stop Loss ranges,
- trailing distances,
- and trailing activation levels
specifically for Gold.
If I copied the same numerical ranges from Euro Yen or Dow Jones, the build would make much less sense.
Risk Reward Ratio Limits
Another parameter I sometimes use is a Risk Reward Ratio limit.
For example, I may allow a range between:
100% and 400%
This gives the build enough freedom to explore different relationships between Take Profit and Stop Loss while still keeping the search inside a reasonable area.
Again, this is not a fixed universal rule.
It is something I experiment with.
The entire build process is iterative.
I test.
I compare the results.
I adjust the ranges.
Then I test again.
The important part is that the adjustments remain logical and connected to the behaviour of the market.
Six Thousand Strategies in the Databank
For these more focused builds, I use a larger databank.
I keep approximately:
6,000 strategies
This gives me a larger population to work with before applying the ranking and retest process.
The strategies are filtered using my standard basic filters.
After that, they move into the retest stage.
Retesting Again Matters
The retest process remains an essential part of the workflow.
I use tick-data retests across:
- In-Sample
- Out-of-Sample
- True Out-of-Sample
The strategies that pass the retest and ranking process are saved into a file.
Then I clear the databank and move on to the next build.
This allows me to keep every project clean and separated.
It also makes the results easier to compare later.
Why I Separate Broad Research from Precision Builds
There are really two different research stages in my process.
The first stage is exploratory.
I want to find out:
- which markets work,
- which timeframes work,
- which templates work,
- and which combinations repeatedly produce good strategy populations.
The second stage is more precise.
Here, I already know which combinations are interesting.
So I can afford to customize:
- Take Profit ranges,
- Stop Loss ranges,
- trailing parameters,
- ATR settings,
- fixed pip ranges,
- and Risk Reward Ratio limits
for the individual market.
This approach is much more efficient than trying to optimize every market from the very beginning.
The Five Markets I Currently Focus On
At this stage of the process, I have five markets where I run more extensive builds.
Each has its own preferred timeframe and strategy logic.
The important point is not the exact list.
The important point is the methodology.
I first let broad research identify the productive combinations.
Then I build dedicated projects around them.
This reduces the research space and allows me to spend more computational power and more time on the markets that actually show potential.
Market Volatility Should Drive the Ranges
If there is one practical idea I would emphasize from this part of the workflow, it is this:
Parameter ranges should reflect the normal volatility and price behaviour of the market.
A Take Profit is not good or bad because it is 100 points.
It only makes sense relative to the market.
The same applies to:
- Stop Loss,
- trailing distance,
- trailing activation,
- and Risk Reward Ratio.
For some instruments, ATR is the most practical way to normalize the parameters.
For others, fixed point or pip ranges work well.
I use both.
Avoid Blind Standardization
Standardization is extremely useful in the first stage of research.
But once you have identified the best combinations, too much standardization can become a limitation.
Markets have different personalities.
They move differently.
Their volatility changes differently.
Their intraday behaviour is different.
That means the final build ranges should respect those characteristics.
The goal is not to create completely different logic for every ticker.
The goal is to keep the research process consistent while allowing the numerical ranges to match the market.
My Current Workflow
The complete process now looks like this:
- Run broad builds across many markets, timeframes, and templates.
- Identify combinations that repeatedly generate strong strategy populations.
- Create dedicated custom projects for these combinations.
- Keep the same In-Sample, Out-of-Sample, and True Out-of-Sample structure.
- Adjust Take Profit and Stop Loss ranges for the specific market.
- Choose between ATR-based and fixed point ranges.
- Configure trailing and trailing activation more precisely.
- Experiment with Risk Reward Ratio limits.
- Keep a larger databank of approximately 6,000 strategies.
- Retest the candidates using tick data.
- Save strategies that pass the retest and ranking process.
- Clear the databank and move on to the next build.
This gives me a much more focused research process.
The Key Idea
The previous article was mainly about identifying which combinations work.
This article is about what happens next.
Once I find a productive combination, I do not simply keep running the same generic build.
I start adapting the build to the actual behaviour of that market.
That means the process gradually moves from:
broad discovery
to:
market-specific research
and finally to:
strategies suitable for deeper validation and potential live trading.
The general framework remains the same.
The ranges become more precise.
And that is the main difference.
What Comes Next
At this point, I have already reduced the research universe significantly.
I know which markets I want to focus on.
I know which timeframes work best.
I know which templates produce the most interesting results.
And I have adapted the basic parameter ranges to the behaviour of each market.
The next step is no longer about generating as many strategies as possible.
It is about validating the best ones much more deeply.
That means robustness testing, parameter stability, additional retests, and deciding which strategies are strong enough to move closer to live deployment.
That will be the topic of the next part.
Disclaimer: This content is for educational and research purposes only. Trading and investing involve substantial risk. Strategy examples, backtests, simulations, and hypothetical results have limitations and do not guarantee future performance. Past performance is not necessarily indicative of future results.